Convert PDF to Images and Vice Versa with JavaScript in React
Images are one of the most intuitive forms of content presentation and distribution, while PDF documents preserve the original layout and are widely used for the storage and transmission of formal files. When displaying PDF content on web pages, mini programs, social platforms, or emails, distributing PDF files directly is often inconvenient — converting them to image formats such as PNG or JPEG first enables quick preview and sharing. Conversely, consolidating scanned documents or image assets into PDF makes batch archiving and cross-platform distribution easier. Real-world business often requires flexible switching between the two forms: converting PDF contracts to images for online preview and quick sharing, or converting scanned image assets to PDF for unified archiving and circulation.
Spire.PDF for JavaScript performs bidirectional conversion between PDF and images entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to Image
The core of PDF-to-image conversion is to render the content, fonts, and graphics elements of every page in a PDF document into independent bitmap data. Spire.PDF for JavaScript generates an image stream for each page through the PdfDocument object's SaveAsImage method, loops through all Pages.Count pages and saves each page as a PNG image with stream.Save, then bundles the images into a ZIP file with JSZip for a one-click download, without needing to handle pixel and page coordinate mapping manually.
import JSZip from "jszip";

function App() {
  const convertToImage = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file and fonts into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Flowers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create an output directory to hold the converted images
    let outputDirectoryName = "ImagesFolders/";
    window.dotnetRuntime.Module.FS.mkdirTree(outputDirectoryName);

    // Loop through each page and save it as an image
    for (let i = 0; i < doc.Pages.Count; i++) {
      const outputFileName = outputDirectoryName + "ConvertedImages_" + i + ".png";
      let stream = doc.SaveAsImage({ pageIndex: i });
      stream.Save(outputFileName);
      stream.Dispose();
    }

    doc.Dispose();

    // Read the converted files from VFS and trigger download
    const zip = new JSZip();
    let items = await window.dotnetRuntime.Module.FS.readdir(outputDirectoryName);
    items = items.filter((item) => item !== "."

      && item !== "..");
    for (const item of items) {
      const itemPath = `${outputDirectoryName}/${item}`;
      const fileData = await window.dotnetRuntime.Module.FS.readFile(itemPath);
      zip.file(item, fileData);
    }

    // Convert the ZIP to a Blob and trigger the browser download
    const zipBlob = await zip.generateAsync({ type: "blob" });
    const url = URL.createObjectURL(zipBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = 'ImagesFolders';
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To Image</h1>
      <button onClick={convertToImage}>
        Generate
      </button>
    </div>
  );
}

export default App;
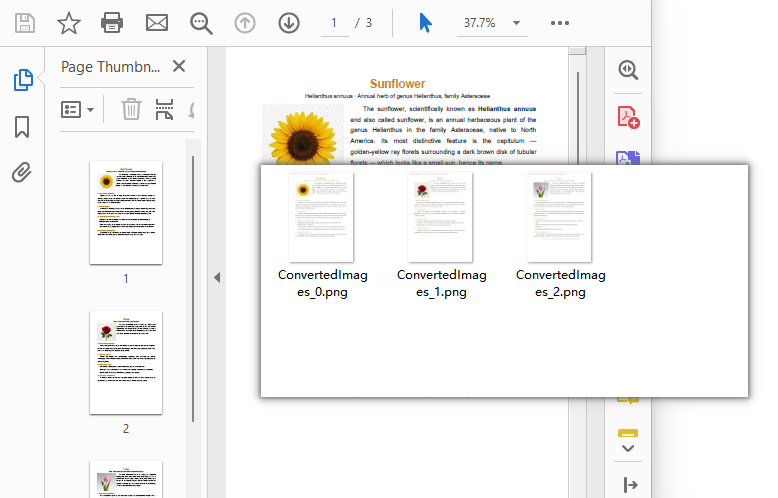
Each page of the PDF exported as a PNG image via SaveAsImage and bundled into a ZIP file for download
Adjust the DPI Resolution of Exported Images
When exporting images with the
SaveAsImagemethod, the default resolution is 96 DPI, which is suitable for screen preview, but text and lines may appear jagged or blurry when zoomed in. For sharper images, specify the resolution via thedpiXanddpiYparameters ofSaveAsImage, for example set it to 150 DPI:
// Export each page as an image at 150 DPI
for (let i = 0; i < doc.Pages.Count; i++) {
  let stream = doc.SaveAsImage({ pageIndex: i, dpiX: 150, dpiY: 150 });
  stream.Save(outputDirectoryName + "highres_" + i + ".png");
  stream.Dispose();
}
The higher the DPI value, the sharper the exported image, but the larger the file size. Choose a balance between clarity and file size based on your actual use case.
Convert Image to PDF
Image-to-PDF conversion is commonly used to consolidate scanned documents or design assets into PDF for archiving. Spire.PDF for JavaScript creates a new document with the PdfDocument object, loads the image with the PdfImage.FromFile method, adds a page via Pages.Add, draws the image onto the page at its original size with the Canvas.DrawImage method, and finally saves it as a standard PDF with the SaveToFile method using the FileFormat.PDF enum value.
function App() {
  const convertImageToPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the image file into VFS
    const inputFileName = 'Scenery.png';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object
    let doc = new pdfModule.PdfDocument();

    // Add a page
    let page = doc.Pages.Add();

    // Load the image
    let image = pdfModule.PdfImage.FromFile(inputFileName);

    // Calculate the scale ratio so the image fits the page completely
    let widthFitRate = image.PhysicalDimension.Width / page.Canvas.ClientSize.Width;
    let heightFitRate = image.PhysicalDimension.Height / page.Canvas.ClientSize.Height;
    let fitRate = Math.max(widthFitRate, heightFitRate);

    // Calculate the scaled dimensions of the image
    let fitWidth = image.PhysicalDimension.Width / fitRate;
    let fitHeight = image.PhysicalDimension.Height / fitRate;

    // Draw the image onto the page
    page.Canvas.DrawImage({ image: image, x: 0, y: 30, width: fitWidth, height: fitHeight });

    const outputFileName = 'ImageToPDF.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.PDF });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Image To PDF</h1>
      <button onClick={convertImageToPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
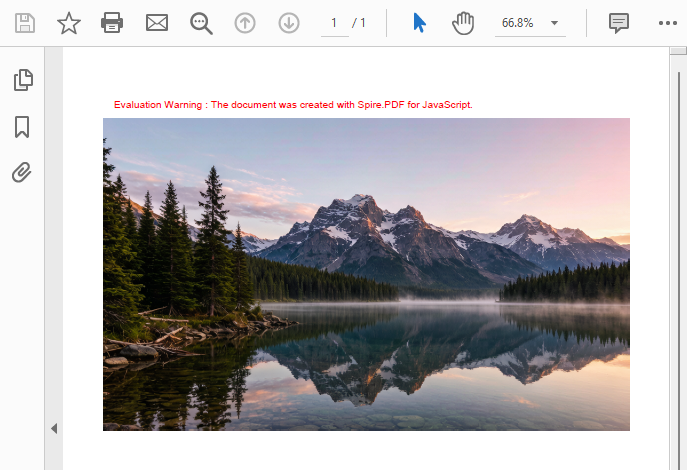
PDF document generated after loading an image via PdfImage.FromFile and drawing it with Canvas.DrawImage
Load Images from a Memory Stream
Besides loading directly from a file with
PdfImage.FromFile, images can also be loaded from a memory stream via thePdfImage.FromStreammethod. This approach suits scenarios where the image data comes from an API response or a database field, or where bytes need to be read before processing. See the code below:
// Read image bytes from VFS and build a memory stream
let bytes = window.dotnetRuntime.Module.FS.readFile(inputFileName);
let stream = new pdfModule.Stream(bytes);

// Load the image from the memory stream
let image = pdfModule.PdfImage.FromStream(stream);
The image can then be drawn onto a PDF page with the page.Canvas.DrawImage method and saved as a standard PDF using SaveToFile.
FAQ
Garbled text in the converted image
Reason: PDF relies on font embedding to ensure consistent cross-platform rendering. If the input PDF uses non-embedded fonts and the corresponding font files are not loaded in the VFS, text may appear garbled after conversion.
Solution: Make sure the required TrueType font files (e.g., ARIALUNI.TTF) are loaded into the /Library/Fonts/ directory in VFS before calling the conversion. ARIALUNI.TTF covers common CJK characters and is the recommended font for ensuring conversion quality.
Which image formats are supported for conversion?
Reason: Different business scenarios require different bitmap formats. For example, PNG is commonly used for web preview and JPEG for photos.
Solution: Spire.PDF for JavaScript can render PDF pages to common bitmap formats such as PNG, JPEG, and BMP. After generating the image stream with SaveAsImage, simply replace the file extension of the output file name with the target format (e.g., .jpg, .bmp, .png) in stream.Save to output the corresponding image format.
Get a Free License
If you want to remove the evaluation messages in the resulting documents or get rid of functional limitations, contact sales to obtain a 30-day temporary license.
Convert PDF to XPS and Vice Versa with JavaScript in React
XPS (XML Paper Specification) is a fixed-layout document format introduced by Microsoft, widely used in electronic document printing, archiving, and distribution scenarios, with native support in the Windows platform ecosystem. XPS describes document structure based on XML, offering advantages such as clear structure, easy validation, and digital signing. Meanwhile, PDF remains indispensable as an internationally recognized document format for cross-platform distribution. Real-world business often requires flexible switching between the two formats: converting existing PDF contracts to XPS for printing and archiving in Windows environments, or converting XPS documents to PDF for cross-platform distribution and collaboration.
Spire.PDF for JavaScript performs bidirectional conversion between PDF and XPS entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to XPS
The core of PDF-to-XPS conversion is to re-encode the page content, fonts, and graphics elements from a PDF document into an XML description structure compliant with the XPS standard. Spire.PDF for JavaScript accomplishes this in one step through the PdfDocument object's SaveToFile method with the FileFormat.XPS enum value, eliminating the need to handle underlying format differences manually.
function App() {
  const convertToXPS = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Reading_EN.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Define the output file name for XPS format
    const outputFileName = 'OutputXPS.xps';

    // Save as XPS format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.XPS });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.ms-xpsdocument' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To XPS</h1>
      <button onClick={convertToXPS}>
        Generate
      </button>
    </div>
  );
}

export default App;
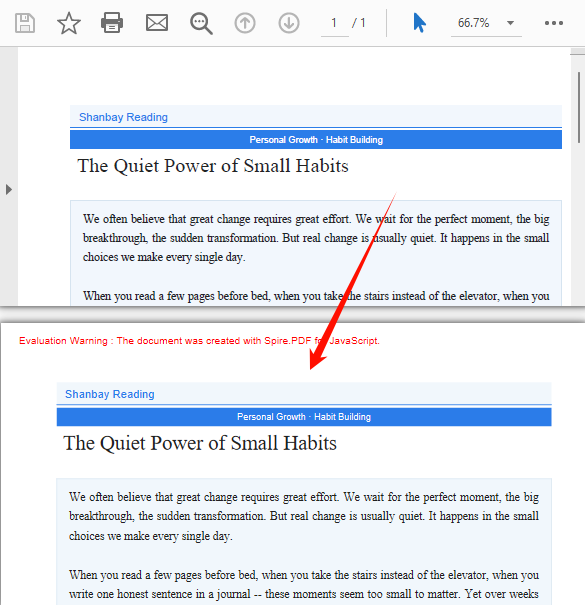
XPS output generated after conversion via SaveToFile with FileFormat.XPS
Convert XPS to PDF
XPS-to-PDF conversion is a common requirement in document cross-platform distribution scenarios. Spire.PDF for JavaScript loads XPS fixed-layout documents through the PdfDocument object's LoadFromXPS method and then exports them as standard PDF files via the SaveToFile method with the FileFormat.PDF enum value, preserving the original document's layout and visual appearance.
function App() {
  const convertXPSToPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the XPS file into VFS
    const inputFileName = 'Lease_Agreement_EN.xps';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the XPS document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromXPS(inputFileName);

    // Define the output file name for PDF format
    const outputFileName = 'OutputPDF.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.PDF });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert XPS To PDF</h1>
      <button onClick={convertXPSToPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
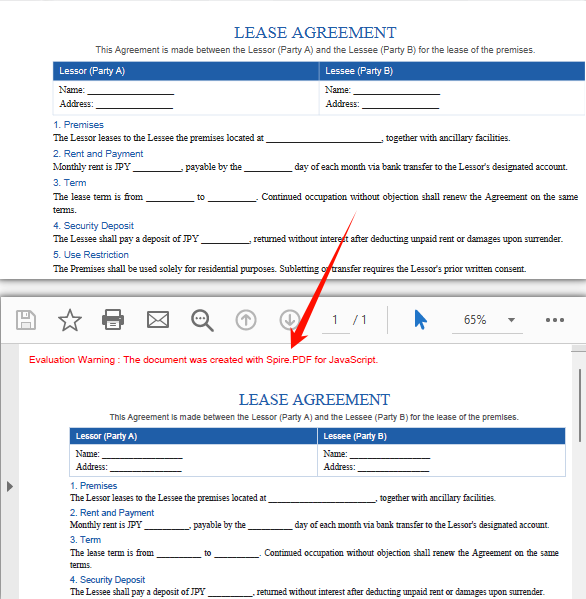
PDF document generated after loading XPS via the PdfDocument LoadFromXPS method and converting
FAQ
Can encrypted PDFs be converted to XPS?
Password-protected encrypted PDFs cannot be saved as XPS directly via SaveToFile — the document must be decrypted first.
Solution: Provide the password when loading the PDF via the second parameter of LoadFromFile, then save as XPS:
// Load a password-protected PDF document
let doc = new pdfModule.PdfDocument();
doc.LoadFromFile(inputFileName, "password");

// Save as XPS format
doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.XPS });
doc.Close();
Get a Free License
If you want to remove the evaluation messages in the resulting documents or get rid of functional limitations, contact sales to obtain a 30-day temporary license.
Convert PDF to OFD and Vice Versa with JavaScript in React
OFD (Open Fixed-layout Document) is a national standard fixed-layout document format widely used in e-invoices, e-certificates, administrative approvals, and other government and financial scenarios. OFD describes document structure based on XML, offering advantages such as independent control and information security. Meanwhile, PDF remains indispensable as an internationally recognized document format for cross-platform distribution. Real-world business often requires flexible switching between the two formats: receiving OFD-format e-invoices and converting them to PDF for printing and distribution, or converting existing PDF contracts to OFD to meet government platform upload requirements.
Spire.PDF for JavaScript performs bidirectional conversion between PDF and OFD entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to OFD
The core of PDF-to-OFD conversion is to re-encode the page content, fonts, and graphics elements from a PDF document into an XML description structure compliant with the OFD standard. Spire.PDF for JavaScript accomplishes this in one step through the PdfDocument object's SaveToFile method with the FileFormat.OFD enum value, eliminating the need to handle underlying format differences manually.
function App() {
  const convertToOFD = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'TemplateIntroduction-en.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Define the output file name for OFD format
    const outputFileName = 'OutputOFD.ofd';

    // Save as OFD format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.OFD });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/ofd' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To OFD</h1>
      <button onClick={convertToOFD}>
        Generate
      </button>
    </div>
  );
}

export default App;
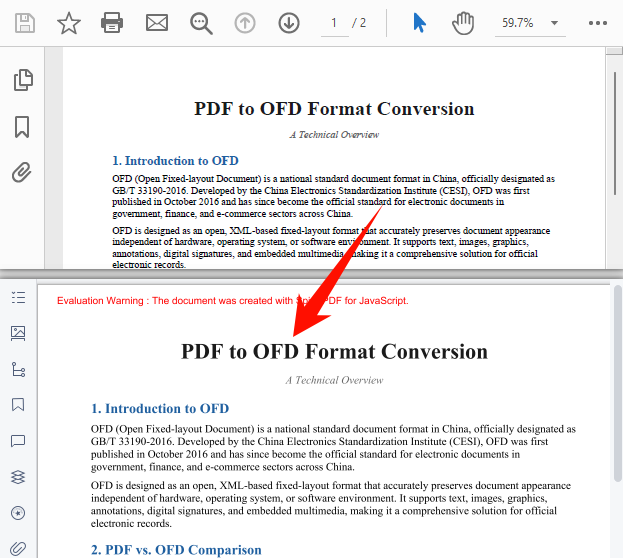
OFD output generated after conversion via SaveToFile with FileFormat.OFD
Convert OFD to PDF
OFD-to-PDF conversion is a common requirement in government electronic document distribution scenarios. Spire.PDF for JavaScript provides the OfdConverter component, which is specifically designed to parse OFD fixed-layout documents and export them as standard PDF files while preserving the original document's layout and visual appearance.
function App() {
  const convertOFDToPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and OFD file into VFS
    await window.spire.FetchFileToVFS('Arial.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Invoice_EN.ofd';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create OfdConverter object and pass the OFD file path
    let converter = new pdfModule.OfdConverter(inputFileName);

    // Define the output file name for PDF format
    const outputFileName = 'OutputPDF.pdf';

    // Convert to PDF format
    converter.ToPdf(outputFileName);
    converter.Dispose();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert OFD To PDF</h1>
      <button onClick={convertOFDToPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
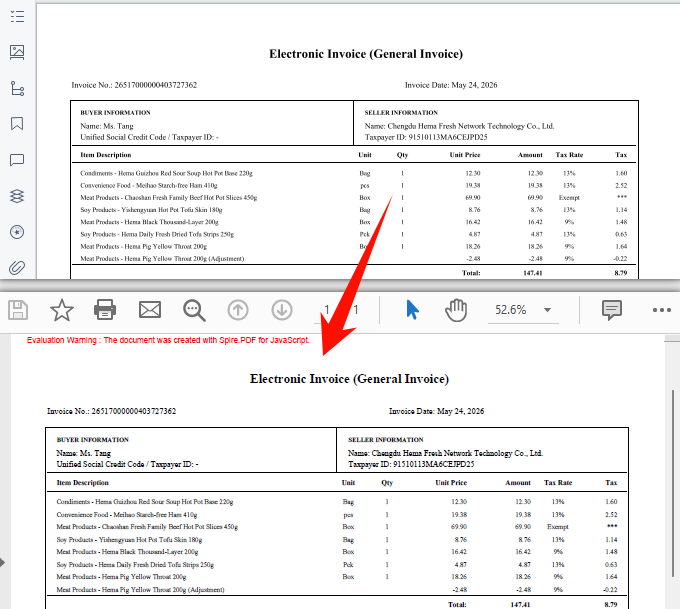
Standard PDF output generated after conversion via OfdConverter
FAQ
Can encrypted PDFs be converted to OFD?
Password-protected encrypted PDFs cannot be saved as OFD directly via SaveToFile — the document must be decrypted first.
Solution: Provide the password when loading the PDF via the second parameter of LoadFromFile, then save as OFD:
// Load a password-protected PDF document
let doc = new pdfModule.PdfDocument();
doc.LoadFromFile(inputFileName, "password");

// Save as OFD format
doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.OFD });
doc.Close();
Garbled text in the converted OFD document
OFD relies on font embedding to ensure consistent cross-platform rendering. If the input PDF uses non-embedded fonts and the corresponding font files are not loaded in the VFS, text may appear garbled after conversion.
Solution: Make sure the required TrueType font files (e.g., ARIALUNI.TTF) are loaded into the /Library/Fonts/ directory in VFS before calling the conversion. ARIALUNI.TTF covers common CJK characters and is the recommended font for ensuring conversion quality.
Get a Free License
Spire.PDF for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Convert PDF to PDF/A and Vice Versa with JavaScript in React
PDF/A is an ISO-standardized long-term archival format that embeds fonts, color profiles, and metadata into a unified compliance level, ensuring documents remain faithfully reproducible for decades regardless of the PDF reader used. In contrast, standard PDF offers greater flexibility for everyday editing and content extraction. Real-world business often requires switching between these two formats: converting contracts to PDF/A for regulatory compliance during archiving, and restoring them to standard PDF for text extraction during audit review.
Spire.PDF for JavaScript performs bidirectional PDF/PDF/A conversion entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to PDF/A
The core of PDF/A archival conversion is to consolidate fonts, color profiles, and metadata in a standard PDF into ISO-compliant levels. Spire.PDF handles this in one step through the PdfStandardsConverter component, supporting multiple compliance levels including PDF/A-1a, PDF/A-1b, PDF/A-2a, PDF/A-2b, PDF/A-3a, and PDF/A-3b.
The conversion standards supported by PdfStandardsConverter and their use cases are as follows:
| Method | Standard | Description |
|---|---|---|
ToPdfA1B |
PDF/A-1b | Based on PDF 1.4, guarantees visual appearance reproducibility only — the most commonly used archival level |
ToPdfA1A |
PDF/A-1a | Requires document tags and structure information on top of 1b, supports accessible reading |
ToPdfA2A |
PDF/A-2a | Based on PDF 1.7, requires tags and structure info, supports layers and transparency |
ToPdfA2B |
PDF/A-2b | PDF/A-2 basic conformance level, allows transparency, layers, and embedded OLE objects |
ToPdfA3A |
PDF/A-3a | Allows embedding XML, Excel, and other arbitrary format files as attachments on top of 2a |
ToPdfA3B |
PDF/A-3b | PDF/A-3 basic conformance level, supports embedding arbitrary format attachments |
ToPdfX1A2001 |
PDF/X-1a:2001 | Print exchange standard, suitable for publishing and printing workflows |
The following example demonstrates converting a PDF to PDF/A-2B using ToPdfA2B:
function App() {
  const convertToPDFA = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('arial.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'MovieCatalog.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfStandardsConverter
    let converter = new pdfModule.PdfStandardsConverter({ filePath: inputFileName });

    // Convert to PDF/A-2B format
    const outputFileName = 'ToPDFA_result.pdf';
    converter.ToPdfA2B({ filePath: outputFileName });

    // // Convert to PDF/A-1a
    // converter.ToPdfA1A({ filePath: outputFileName });

    // // Convert to PDF/A-2a
    // converter.ToPdfA2A({ filePath: outputFileName });

    // // Convert to PDF/A-2b
    // converter.ToPdfA2B({ filePath: outputFileName });

    // // Convert to PDF/A-3a
    // converter.ToPdfA3A({ filePath: outputFileName });

    // // Convert to PDF/A-3b
    // converter.ToPdfA3B({ filePath: outputFileName });

    // // Convert to PDF/X-1a:2001
    // converter.ToPdfX1A2001({ filePath: outputFileName });

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    converter.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To PDF/A</h1>
      <button onClick={convertToPDFA}>
        Generate
      </button>
    </div>
  );
}

export default App;
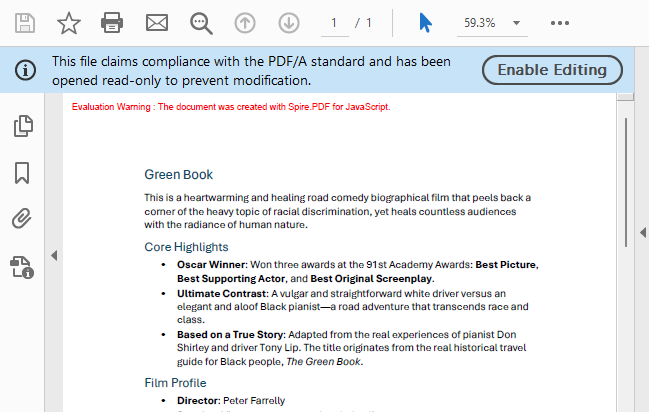
PDF/A output generated after conversion via PdfStandardsConverter
Convert PDF/A to PDF
PDF/A is the standard format for long-term archiving, but in everyday editing and content extraction scenarios, you may need to restore PDF/A back to standard PDF. Spire.PDF for JavaScript achieves this reverse conversion by loading the PDF/A document and copying content page by page into a new document, ensuring the output standard PDF is free of PDF/A compliance constraints.
function App() {
  const convertToNormalPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('arial.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'PDFA_Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create a new PDF document to draw content onto
    let newDoc = new pdfModule.PdfNewDocument();
    newDoc.CompressionLevel = pdfModule.PdfCompressionLevel.None;

    // Iterate through each page in the original document
    for (let i = 0; i < doc.Pages.Count; i++) {
      let page = doc.Pages.get_Item(i);
      // Get the current page size
      let size = page.Size;

      // Add a new page with the same size and no margins
      let newPage = newDoc.Pages.Add({ size: size, margins: new pdfModule.PdfMargins() });

      // Draw the original page content onto the new page
      let template = page.CreateTemplate();
      let layoutWidget = new pdfModule.PdfLayoutWidget(template.H);
      layoutWidget.Draw({ page: newPage, x: 0, y: 0 });
      // page.CreateTemplate().Draw({page: newPage, x: 0, y: 0});
    }

    // Define the output file name
    const outputFileName = "PDFAToPdf_result.pdf";

    // Save the document to the specified path
    newDoc.Save(outputFileName);

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    newDoc.Dispose();
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF/A To Normal PDF</h1>
      <button onClick={convertToNormalPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
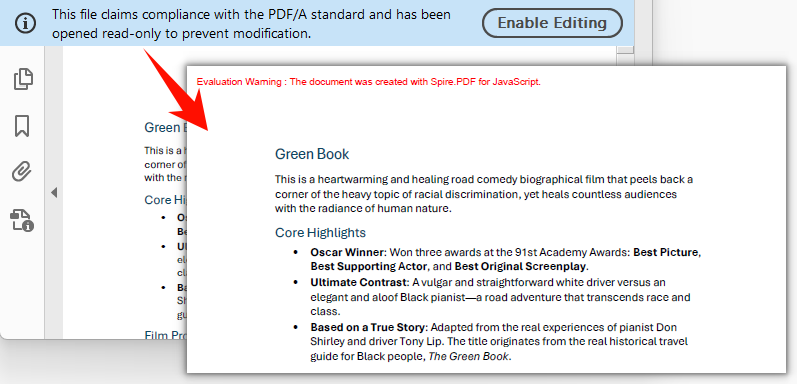
Standard PDF output generated by creating a new document and copying pages
FAQ
Converted PDF/A file size is much larger than the original
PDF/A requires all fonts used in the document to be fully embedded to ensure correct rendering on any device. If the original document uses non-embedded system fonts, the font data will be written completely into the output file during conversion, resulting in a larger file size. This is an inherent requirement of PDF/A compliance. To minimize file size, consider using font subsetting (embedding only the characters actually used) or compressing image content before generating the source PDF.
Can encrypted PDFs be converted to PDF/A?
Encrypted PDFs that require a password to open cannot be processed directly by PdfStandardsConverter. The password must be provided when loading the document.
The PdfStandardsConverter constructor supports a password parameter for converting password-protected PDFs to PDF/A:
// Create PdfStandardsConverter with password
let converter = new pdfModule.PdfStandardsConverter({ filePath: inputFileName, password: "123456" });
converter.ToPdfA2A({ filePath: outputFileName });
converter.Dispose();
"File not found" or "Invalid PDF format" error when loading PDF/A
PDF/A documents must first be converted via PdfStandardsConverter, or properly loaded into the virtual file system (VFS) via FetchFileToVFS. Common mistakes include passing the wrong file name or path, or executing subsequent operations before the file has finished loading. Verify that the file has been loaded into VFS via FetchFileToVFS and that the file name (including extension) matches exactly. Use await to ensure the file is ready before proceeding.
Get a Free License
Spire.PDF for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Get, Replace, Delete Word Bookmark Content and Insert Elements with JavaScript in React
Bookmarks are invisible positioning markers in Word documents that act as coordinates, precisely marking a location or a range of text. But the true value of bookmarks goes beyond positioning—by programmatically retrieving content within a bookmark range, replacing placeholder text, removing unwanted content, or inserting text, paragraphs, tables, and images at bookmark positions, developers can implement advanced document processing workflows such as automatic contract template filling, dynamic report data injection, and batch form content cleanup. The combination of "read, write, delete, and insert" operations around bookmark content forms the core of Word automation.
Spire.Doc for JavaScript runs entirely in the browser via WebAssembly, handling bookmark content retrieval, replacement, deletion, and element insertion directly — all managed through a virtual file system (VFS) with no backend server required.
This article covers four core features:
- Get Bookmark Content
- Replace Bookmark Content
- Delete Bookmark Content
- Insert Text, Paragraphs, Tables, and Images at a Bookmark
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume Spire.Doc is installed and the WebAssembly module is initialized.
Get Bookmark Content
Getting bookmark content is the prerequisite for any bookmark operation. After locating a bookmark with BookmarksNavigator, the GetBookmarkContent method returns the content within the bookmark range as a TextBodyPart object, which developers can iterate through its BodyItems collection to retrieve elements.
function App() {
  const bookmarkContent = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the WASM module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Word file into VFS
    const inputFileName = 'ContractTemplate_en.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the Word document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Create a BookmarksNavigator and move to the bookmark
    let navigator = new docModule.BookmarksNavigator(doc);
    navigator.MoveToBookmark("myBookmark");
    let textBodyPart = navigator.GetBookmarkContent();

    // Iterate through elements in the bookmark content and extract text
    let text = "";
    for (let i = 0; i < textBodyPart.BodyItems.Count; i++) {
      let item = textBodyPart.BodyItems.get_Item(i);
      if (item instanceof docModule.Paragraph) {
        for (let j = 0; j < item.ChildObjects.Count; j++) {
          let childObject = item.ChildObjects.get_Item(j);
          if (childObject instanceof docModule.TextRange) {
            text += childObject.Text;
          }
        }
      }
    }

    // Save as a .txt file
    const outputFileName = "GetBookmarkContent.txt";

    // Write the text file to VFS and trigger download
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, text);

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Get Bookmark Content from Word Document</h1>
      <button onClick={bookmarkContent}>
        Generate
      </button>
    </div>
  );
}

export default App;
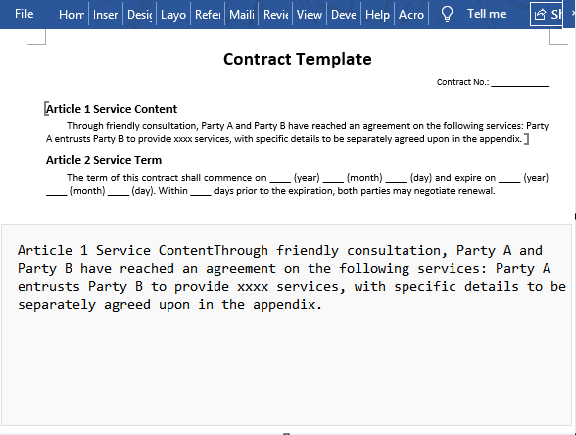
Executing the code above extracts the text content from the bookmark "myBookmark" and saves it as a separate .txt file:
Replace Bookmark Content
Replacing bookmark content is the most common operation in document template filling. After locating a bookmark with BookmarksNavigator, the ReplaceBookmarkContent method supports replacement with both plain text and complex elements like tables, making it ideal for placeholder replacement in contract generation, report filling, and similar scenarios.
function App() {
  const replaceBookmarkContent = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the WASM module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load fonts and Word file into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'BookmarkSample.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the Word document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Create a BookmarksNavigator and move to the bookmark
    let navigator = new docModule.BookmarksNavigator(doc);
    navigator.MoveToBookmark("Bookmark1");

    // Replace the content of "书签1" — with text
    navigator.ReplaceBookmarkContent({ text: "This is the text that will replace the bookmark.", saveFormatting: true });

    // Continue to replace "书签2" — with a table
    navigator.MoveToBookmark("Bookmark2");

    // Create a table
    let table = new docModule.Table(doc, true);
    table.ResetCells(4, 5);

    // Create data and fill it into the table
    let dt = [
      ["City", "Province", "Population", "Area (km²)", "Abbrev."],
      ["Beijing", "Beijing", "21.89M", "16410", "BJ"],
      ["Shanghai", "Shanghai", "24.75M", "6340", "SH"],
      ["Guangzhou", "Guangdong", "18.67M", "7434", "GZ"]];
    for (let i = 0; i < 4; i++) {
      for (let j = 0; j < 5; j++) {
        table.Rows.get_Item(i).Cells.get_Item(j).AddParagraph().AppendText(dt[i][j]);
      }
    }

    // Create a TextBodyPart instance and add the table to it
    let part = new docModule.TextBodyPart({ doc: doc });
    part.BodyItems.Add(table);

    // Replace the current bookmark content with the TextBodyPart
    navigator.ReplaceBookmarkContent({ bodyPart: part });

    // Save as a new .docx file
    const outputFileName = "ReplaceBookmark.docx";
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace Bookmark Content in Word</h1>
      <button onClick={replaceBookmarkContent}>
        Generate
      </button>
    </div>
  );
}

export default App;
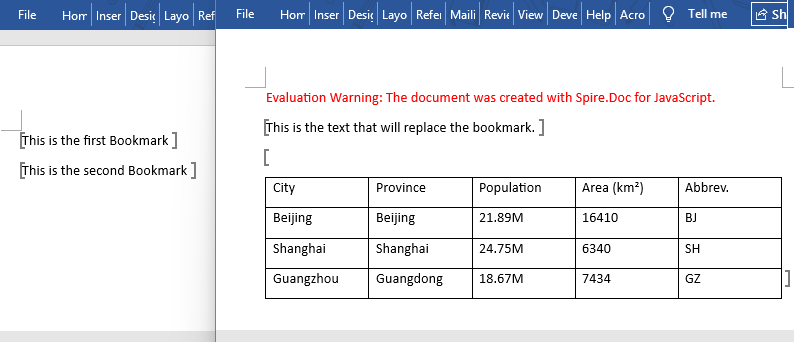
This method supports replacing bookmark content with plain text or complex elements like tables. The bookmark marker itself is preserved after replacement, making it easy to locate again later. The figure below shows the result:
Delete Bookmark Content
Deleting bookmark content and removing a bookmark marker are two different operations. After locating a bookmark with BookmarksNavigator, calling DeleteBookmarkContent removes the text content within the bookmark range while preserving the bookmark marker itself for later refilling. If you only need to clear the content while keeping the positioning marker, this method is the preferred choice.
function App() {
  const deleteBookmarkContent = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the WASM module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Word file into VFS
    const inputFileName = 'ContractTemplate_en.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the Word document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Create a BookmarksNavigator and move to the bookmark
    let navigator = new docModule.BookmarksNavigator(doc);
    navigator.MoveToBookmark("myBookmark");

    // Delete bookmark content, keep the bookmark marker
    navigator.DeleteBookmarkContent(true);

    // Save as a new .docx file
    const outputFileName = "RemoveBookmark.docx";

    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Bookmark Content in Word</h1>
      <button onClick={deleteBookmarkContent}>
        Generate
      </button>
    </div>
  );
}

export default App;
DeleteBookmarkContentremoves only the text content within the bookmark range — the bookmark marker itself remains.Bookmarks.Remove, on the other hand, removes the bookmark marker, leaving the text within the range unaffected.
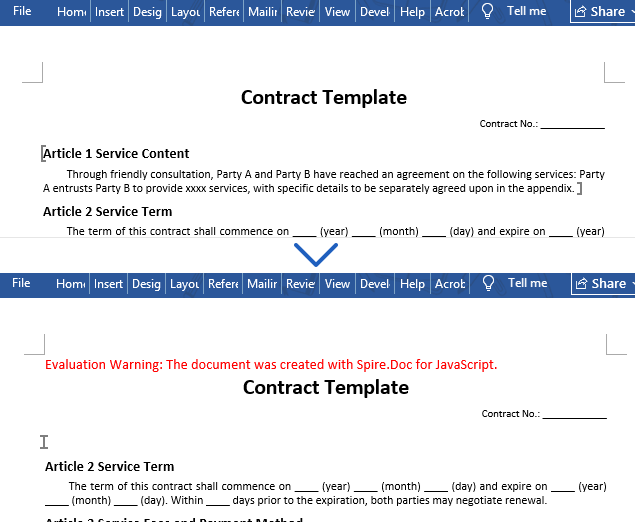
After execution, the text within the bookmark "myBookmark" is removed, but the bookmark marker stays in the document:
Insert Text, Paragraphs, Tables, and Images at a Bookmark
Spire.Doc supports flexibly inserting various types of document elements at bookmark positions. It provides InsertText, InsertParagraph, and InsertTable methods for inserting text, paragraphs, and tables. Elements can also be inserted based on the index of the bookmark start node within the paragraph's ChildObjects collection.
function App() {
  const insertElementsAtBookmark = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the WASM module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load fonts and Word file into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'BookmarkSample1.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a Document object and load the file
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Move to the bookmark position
    let navigator = new docModule.BookmarksNavigator(doc);
    navigator.MoveToBookmark("Bookmark1");

    // 1. Insert text
    navigator.InsertText("This is the inserted text content.", true);

    // 2. Insert paragraph
    let newParagraph = new docModule.Paragraph(doc);
    newParagraph.AppendText("This is the inserted paragraph content.")
    navigator.MoveToBookmark("Bookmark2");
    navigator.InsertParagraph(newParagraph);

    // 3. Insert table — 2 rows, 3 columns
    let table = new docModule.Table(doc, true);
    table.ResetCells(2, 3);
    table.Rows.get_Item(0).Cells.get_Item(0).AddParagraph().AppendText("Name");
    table.Rows.get_Item(0).Cells.get_Item(1).AddParagraph().AppendText("Quantity");
    table.Rows.get_Item(0).Cells.get_Item(2).AddParagraph().AppendText("Note");
    table.Rows.get_Item(1).Cells.get_Item(0).AddParagraph().AppendText("Product A");
    table.Rows.get_Item(1).Cells.get_Item(1).AddParagraph().AppendText("100");
    table.Rows.get_Item(1).Cells.get_Item(2).AddParagraph().AppendText("In Stock");

    navigator.MoveToBookmark("Bookmark3");
    navigator.InsertTable(table);

    // 4. Insert image
    const imageFileName = 'pic.png';
    await window.spire.FetchFileToVFS(imageFileName, '', `${process.env.PUBLIC_URL}/data/`);
    let picture = new docModule.DocPicture(doc);
    picture.LoadImage(imageFileName);
    picture.Width = 100;
    picture.Height = 200;

    navigator.MoveToBookmark("Bookmark4");
    // Get the bookmark start node
    let start = navigator.CurrentBookmark.BookmarkStart;
    // Get the paragraph containing the bookmark
    let bookmarkPara = start.OwnerParagraph;
    // Get the index of the bookmark start node in the paragraph
    let startIndex = bookmarkPara.ChildObjects.IndexOf(start);
    // Insert the image after the bookmark start node
    bookmarkPara.ChildObjects.Insert(startIndex + 1, picture);

    // Save as a .docx file
    const outputFileName = "InsertToBookmark.docx";

    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release Document resources
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Insert Elements at Bookmark Position</h1>
      <button onClick={insertElementsAtBookmark}>
        Generate
      </button>
    </div>
  );
}

export default App;
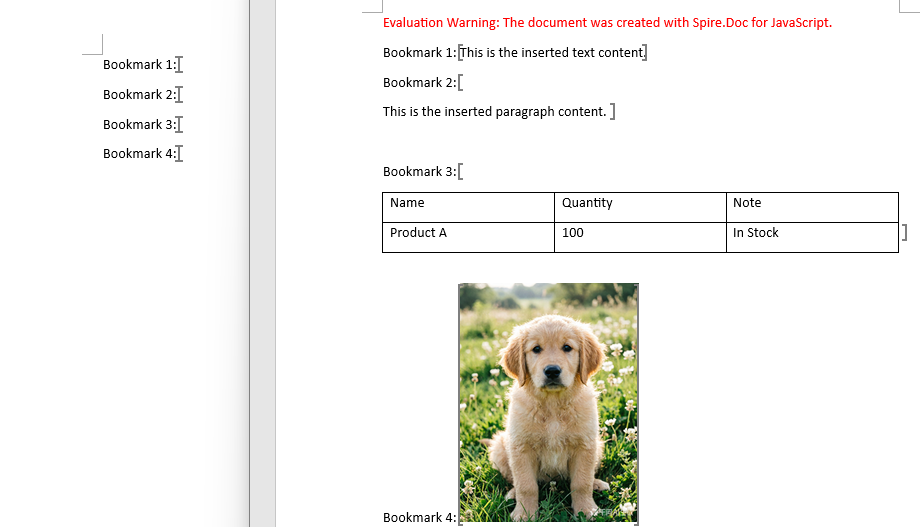
The figure below shows the generated document with text, paragraph, table, and image inserted at bookmark positions:
FAQ
Formatting (font, size, color) is lost after replacing bookmark content — how to keep it?
ReplaceBookmarkContent replaces with plain text by default, discarding the original formatting. To preserve the bookmark's existing formatting, pass saveFormatting: true:
navigator.ReplaceBookmarkContent({ text: "New content", saveFormatting: true });
The replacement text will then inherit the original font, size, color, and other formatting from the bookmark.
How to batch process multiple bookmarks in a document?
Iterate through the doc.Bookmarks collection, locating and operating on each bookmark one by one:
for (let i = 0; i < doc.Bookmarks.Count; i++) {
    let bookmark = doc.Bookmarks.get_Item(i);
    navigator.MoveToBookmark(bookmark.Name);
    // Perform replace, delete, or insert operations
}
What's the difference between DeleteBookmarkContent and removing a bookmark marker?
DeleteBookmarkContent: Clears only the content within the bookmark range. The bookmark marker stays in the document, so you can still locate it by name and fill in new content later.Bookmarks.Remove: Removes the bookmark marker itself. The content within the bookmark range is unaffected, but the bookmark name disappears and can no longer be located.
Choose the appropriate operation based on your needs: use DeleteBookmarkContent if you need to keep the "placeholder" capability, or remove the marker if the bookmark is no longer needed.
When inserting multiple elements at the same bookmark, why does only the last one take effect?
Methods like InsertText, InsertParagraph, and InsertTable insert based on the bookmark's current position. When inserting multiple times at the same bookmark, subsequent insertions may overwrite or shift previously inserted content. It is recommended to use separate bookmarks for each insertion, or re-locate the bookmark after each insert before proceeding with the next operation.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Add and Remove Word Bookmarks with JavaScript in React
A bookmark is like an invisible "anchor" in a Word document, able to accurately locate a specific position or selected text. Whether it's a fill-in area in a contract template, a key section to jump to in a long document, or a data insertion point when generating reports in batch, bookmarks are the critical anchor behind these operations. Developers can use bookmarks for dynamic content filling, navigation, content extraction, and other advanced features, making bookmark management one of the most commonly used capabilities in Word automation.
Spire.Doc for JavaScript runs entirely in the browser via WebAssembly, handling bookmark creation, navigation, and deletion directly — all managed through a virtual file system (VFS) with no backend server required.
This article covers three core features:
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume Spire.Doc is installed and the WebAssembly module is initialized.
Add a Bookmark to a Paragraph
To add a bookmark in an existing document, use AppendBookmarkStart and AppendBookmarkEnd to mark the bookmark region on a paragraph. You can add bookmark markers to existing paragraphs or append a new paragraph with a bookmark. Spire.Doc also supports nested bookmarks for building hierarchical structures.
function App() {
  const createBookmarkInWord = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Word file into VFS
    const inputFileName = 'ChinaTravelGuide.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Get the first section and add bookmarks
    let section = doc.Sections.get_Item(0);

    AddBookmark(section);

    // Save as a .docx file
    const outputFileName = "AddBookmark.docx";

    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    doc.Dispose();
  };

  function AddBookmark(section) {
    // Bookmark 1: add bookmark markers around existing paragraphs
    let paraStart = section.Paragraphs.get_Item(1);
    let paraEnd = section.Paragraphs.get_Item(3);

    paraStart.AppendBookmarkStart("Bookmark1");
    paraEnd.AppendBookmarkEnd("Bookmark1");

    // Bookmark 2: add a new paragraph with a bookmark
    let paragraph = section.AddParagraph();
    paragraph.AppendBookmarkStart("Bookmark2");
    paragraph.AppendText("This is a new paragraph");
    paragraph.AppendBookmarkEnd("Bookmark2");
  }

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Bookmark in Word</h1>
      <button onClick={createBookmarkInWord}>
        Generate
      </button>
    </div>
  );
}

export default App;
Bookmarks added to the generated Word document

Add a Bookmark to Selected Text
To add a bookmark to specific text within an existing paragraph, first locate the text with FindAllString, create bookmark objects using the BookmarkStart and BookmarkEnd constructors, then insert the start marker before and the end marker after the matched TextRange via ChildObjects.Insert.
function App() {
  const addBookmarkForMatchedText = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the WASM module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Word file into VFS
    const inputFileName = 'ChinaTravelGuide.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the Word document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Find all occurrences of "Street" in the document
    let textSelections = doc.FindAllString('Street', false, true);

    // Iterate over each match and insert bookmark start/end markers
    for (let i = 0; i < textSelections.length; i++) {

      // Create bookmark start and end objects (named "Bookmark_0", "Bookmark_1", ...)
      let start = new docModule.BookmarkStart(doc, "Bookmark_" + i);
      let end = new docModule.BookmarkEnd(doc, "Bookmark_" + i);

      let selection = textSelections[i];

      // Get the TextRange of the matched text
      let textRange = selection.GetAsOneRange();

      // Get the paragraph containing the matched text
      let para = textRange.OwnerParagraph;

      // Get the index of the TextRange within the paragraph's child objects
      let index = para.ChildObjects.IndexOf(textRange);

      // Insert the bookmark start before the TextRange and the bookmark end after it
      para.ChildObjects.Insert(index, start);
      para.ChildObjects.Insert(index + 2, end);
    }

    // Save as a new .docx file
    const outputFileName = "AddBookmark.docx";

    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release document resources
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Bookmarks for Specific Text in Word Documents</h1>
      <button onClick={addBookmarkForMatchedText}>
        Generate
      </button>
    </div>
  );
}

export default App;
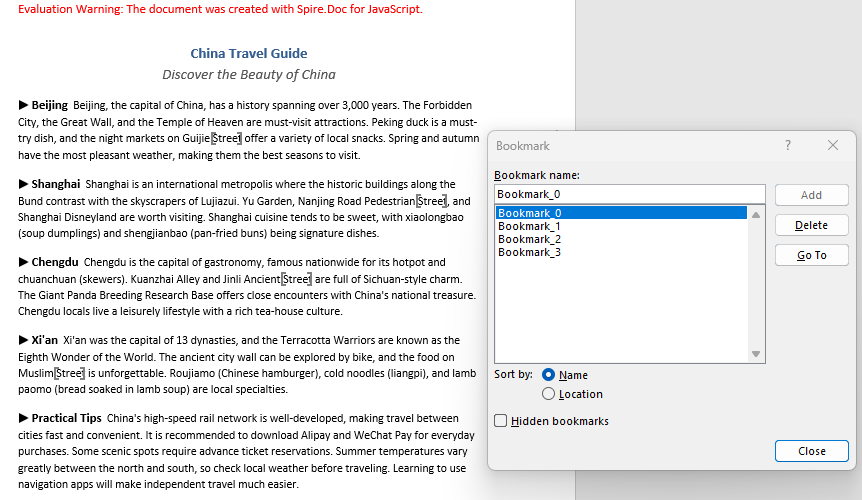
This approach is ideal for scenarios where you need to add positioning markers on top of an existing document, such as marking fill-in areas in a completed contract. The figure below shows the result after execution:
Remove a Bookmark
Removing a bookmark only removes the bookmark markers themselves — the text content within the bookmark range is preserved. Retrieve the bookmark object from the document.Bookmarks collection, then call the Remove method to delete it.
function App() {
  const deleteBookmark = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the WASM module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Word file into VFS
    const inputFileName = 'AddBookmark.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the Word document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Get the bookmark by name
    let bookmark = doc.Bookmarks.get_Item("Bookmark_1");

    // // Get the bookmark by index
    // let bookmark = doc.Bookmarks.get_Item(0);

    // Remove the bookmark (keep its content)
    doc.Bookmarks.Remove(bookmark);

    // Save as a new .docx file
    const outputFileName = "DeleteBookmark.docx";

    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release document resources
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Bookmark in Word Document</h1>
      <button onClick={deleteBookmark}>
        Generate
      </button>
    </div>
  );
}

export default App;
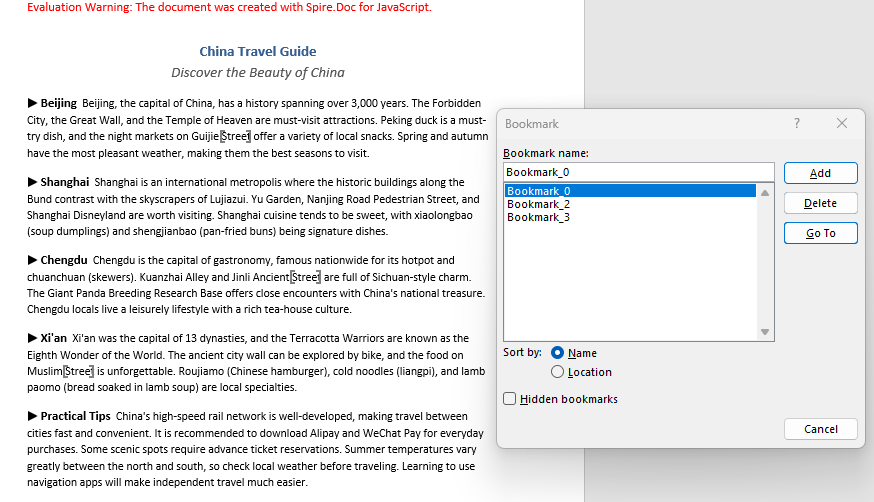
After the bookmark is removed, its markers disappear from the document, but the text within the bookmark range is preserved.
FAQ
Duplicate bookmark name error
Cause: Bookmark names must be unique within a Word document. Adding a bookmark with a duplicate name causes an error.
Solution: Check whether the name already exists before adding the bookmark:
if (document.Bookmarks.FindByName("MyBookmark") === null) {
    paragraph.AppendBookmarkStart("MyBookmark");
    paragraph.AppendText("Content");
    paragraph.AppendBookmarkEnd("MyBookmark");
}
What is the difference between removing a bookmark and deleting its content?
Cause: Spire.Doc's Bookmarks.Remove only removes the bookmark markers (start and end), leaving the text content between them untouched.
Solution: Choose the appropriate operation based on your needs:
// Remove only the bookmark markers, keep the text
document.Bookmarks.Remove(bookmark);

// Remove the bookmark and its content (via BookmarksNavigator)
let navigator = new docModule.BookmarksNavigator(doc);
navigator.MoveToBookmark("MyBookmark");
navigator.DeleteBookmarkContent();
Do AppendBookmarkStart and AppendBookmarkEnd have to be on the same paragraph?
Cause: The start and end markers can be on different paragraphs — the "Bookmark1" example in the code above demonstrates cross-paragraph usage. The key constraint is that the document object structure within the bookmark range must remain intact. Bookmarks cannot span across table cells, since cells are independent containers and doing so may cause the bookmark to be unrecognized.
Solution: If the bookmark range crosses a table cell boundary, adjust the start or end position so that the bookmark closes within the same cell.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Convert Excel to SVG with JavaScript in React
Exporting Excel worksheets and charts to SVG vector graphics lets you display data clearly at any resolution on the web, while keeping text selectable and searchable. Spire.XLS for JavaScript runs entirely in the browser via WebAssembly, using a virtual file system (VFS) to manage input and output files — no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.XLS for JavaScript in a React Project. The examples below assume Spire.XLS is installed and the WebAssembly module is initialized.
Worksheet to SVG
Converting a worksheet to SVG involves three steps: first, load the font files and the target Excel file into the WASM virtual file system via FetchFileToVFS; then instantiate a Workbook, load the file, retrieve the target worksheet, and call ToSVGStream to render it into a Stream object; finally, read the generated SVG file from VFS, wrap it as a Blob, and trigger a browser download.
function App() {
  const sheetToSVG = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load fonts and the Excel file into VFS
    await window.spire.FetchFileToVFS('arial.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'ImageHeaderFooter.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Load the workbook and get the first worksheet
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });
    const sheet = workbook.Worksheets.get(0);

    // Convert the worksheet to an SVG stream
    const outputFileName = "Worksheet.svg";
    let fs = new xlsModule.Stream(outputFileName);
    sheet.ToSVGStream(fs, 0, 0, 0, 0);
    fs.Flush();
    fs.Dispose();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "image/svg+xml;charset=utf-8"});
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    workbook.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Excel To SVG</h1>
      <button onClick={sheetToSVG}>
        Generate
      </button>
    </div>
  );
}

export default App;
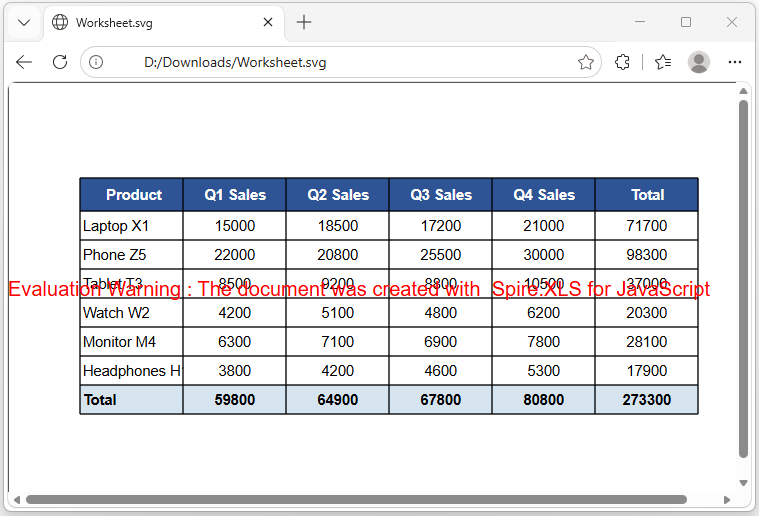
SVG output generated from a worksheet via ToSVGStream
ChartSheet to SVG
A ChartSheet is a special type of worksheet that contains an embedded chart instead of cell data. The conversion process is similar to worksheet-to-SVG, with two key differences: retrieve the chartsheet by name using GetChartSheetByName("Chart1") instead of by index; and call ToSVGStream(fs) without specifying cell range parameters, since the rendering area is determined by the chart itself.
function App() {
  const chartsheetToSVG = async () => {
    // Get the Spire.XLS WASM module
    const xlsModule = window.wasmModule?.spirexls;

    // Check if the module is ready
    if (!xlsModule) {
      alert('Spire.Xls is not ready yet');
      return;
    }

    // Load fonts and the Excel file into VFS
    await window.spire.FetchFileToVFS('arial.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'ChartSheet.xlsx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Load the workbook
    const workbook = new xlsModule.Workbook();
    workbook.LoadFromFile({ fileName: inputFileName });

    // Get the chartsheet by name
    let cs = workbook.GetChartSheetByName("Chart1");

    // Define the output file name
    const outputFileName = 'ChartSheetToSVG-out.svg';

    // Create a stream and convert the chartsheet to SVG
    const fs = new xlsModule.Stream(outputFileName);
    cs.ToSVGStream(fs);
    fs.Flush();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "image/svg+xml;charset=utf-8" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    workbook.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Chartsheet To SVG</h1>
      <button onClick={chartsheetToSVG}>
        Generate
      </button>
    </div>
  );
}

export default App;
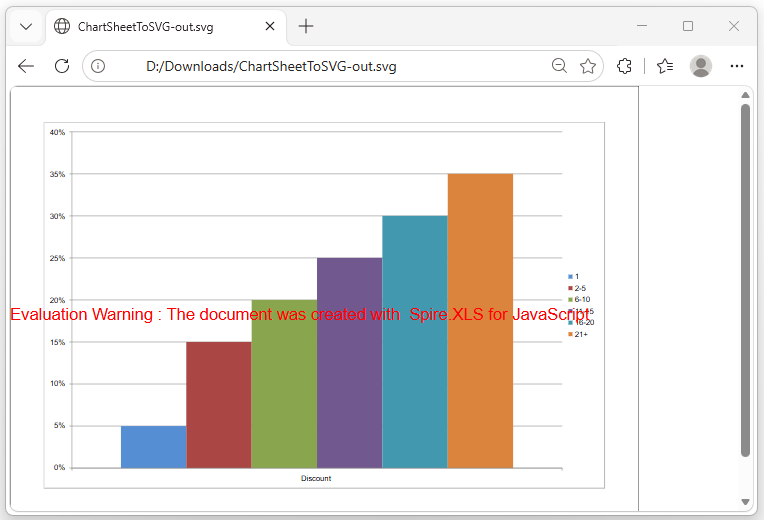
SVG output generated from a chartsheet via ToSVGStream
SVG vs PNG Comparison
| Feature | SVG | PNG |
|---|---|---|
| Scaling Quality | Sharp at any zoom | Blurry when enlarged |
| Text | Selectable and searchable | Rasterized (flat image) |
| File Size | Small (a few KB) | Large at high resolutions |
| CSS Styling | Supports inline styles | Not supported |
| Post-processing | Editable in Illustrator, Inkscape | Requires pixel-level editing |
| Browser Embedding | <img> or <embed> |
<img> tag |
Recommendation: Use SVG for web reports or scenarios where selectable text matters; use PNG when compatibility with image editors or legacy systems is required.
FAQ
Missing or garbled SVG text
Cause: The required font files are not present in the WASM virtual file system. ToSVGStream reads fonts from VFS when rendering text — if fonts are not preloaded, text areas will appear blank or garbled.
Solution: Load the font files into VFS via FetchFileToVFS before conversion:
await window.spire.FetchFileToVFS(
  'ARIAL.TTF', '/Library/Fonts/', '/'
);
SVG file cannot be opened or appears corrupted
Cause: The MIME type is incorrect when creating the Blob, so the browser cannot properly identify the file format.
Solution: Use the correct SVG MIME type:
const blob = new Blob([data], {
  type: "image/svg+xml;charset=utf-8"
});
Get a Free License
Spire.XLS for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Add, Replace, Delete, or Extract Images in PDF with JavaScript in React
Product images, screenshots, charts, and stamps in a PDF often need to be updated or reused: inserting new images into a PDF, replacing an old Logo with a new Logo, deleting outdated illustrations, or extracting images from a PDF for use in other documents. Because the PDF layout is fixed, directly modifying these images with an editor is often very difficult.
Spire.PDF for JavaScript processes PDF documents directly in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required. With PdfImage, the DrawImage method of the page canvas, and the PdfImageHelper helper class, you can easily add, replace, delete, and extract images in PDFs.
This article covers four core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Add Images to a PDF
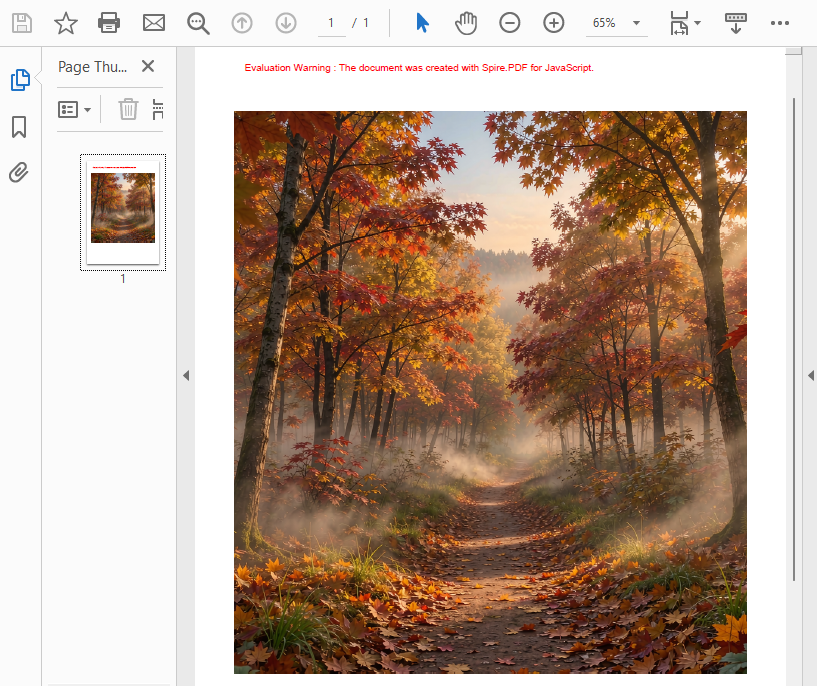
Adding images is one of the most common image operations. The core idea is: first load the image file with the PdfImage.FromFile method, then use the DrawImage method of the page canvas to draw the image at a specified position and size on the page. The x and y parameters determine the coordinates of the top-left corner of the image, and the width and height parameters determine the display size of the image. You can add an image to a specified page of an existing document, or draw the image in a new blank document as in the example below.
function App() {
  const addImageToPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the image into VFS
    const inputImageName = 'TreePic.png';
    await window.spire.FetchFileToVFS(inputImageName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object
    let doc = new pdfModule.PdfDocument();

    // Add a page
    let page = doc.Pages.Add();

    // Load the image and scale its display size proportionally
    let image = pdfModule.PdfImage.FromFile(inputImageName);
    let width = image.Width * 0.6;
    let height = image.Height * 0.6;

    // Calculate the horizontal center position and set the vertical position
    let x = (page.Canvas.ClientSize.Width - width) / 2;
    let y = 60;

    // Draw the image at the specified position on the page
    page.Canvas.DrawImage({ image: image, x: x, y: y, width: width, height: height });

    // Define the output file name in PDF format
    const outputFileName = 'AddImage.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName });
    doc.Close();

    // Read the generated PDF file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Image To PDF</h1>
      <button onClick={addImageToPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document generated after adding an image
Replace Images in a PDF
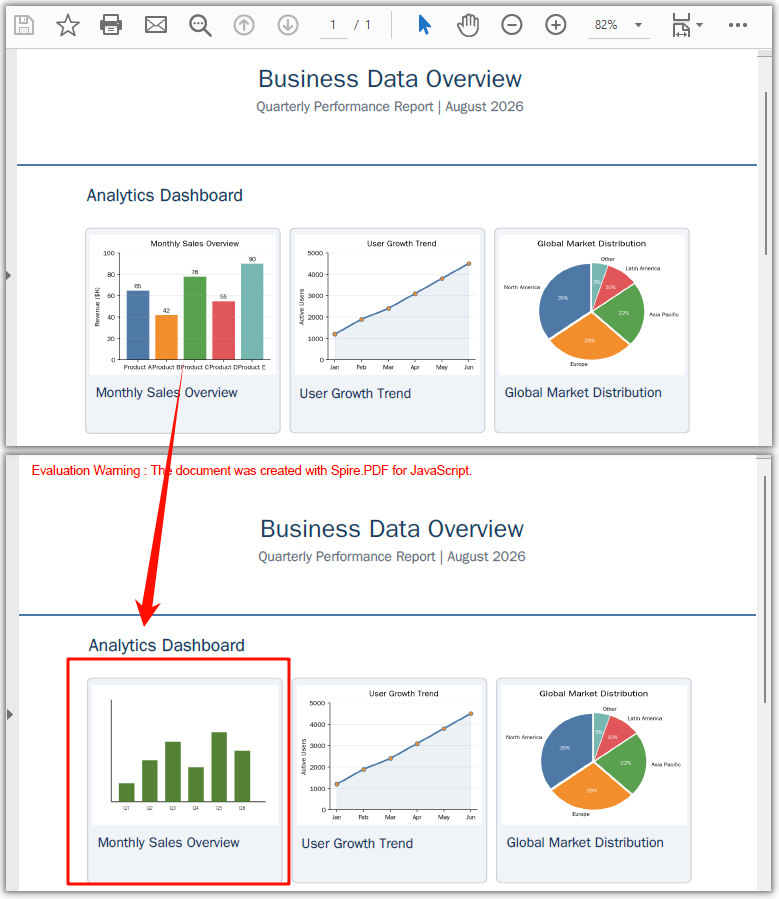
Replacing an image means replacing the content of an image on the page with a new image while keeping the original position and placeholder size unchanged. First, use the GetImagesInfo method of PdfImageHelper to get the array of image information on the page, then load the new image, and call the ReplaceImage method to replace the image at the specified index with the new image. After replacement, the new image automatically inherits the original image's position and size on the page, so the overall layout remains unchanged.
function App() {
  const replaceImageInPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Load the new image used for replacement into VFS
    const newImageName = 'ChartImage.png';
    await window.spire.FetchFileToVFS(newImageName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the first page
    let page = doc.Pages.get_Item(0);

    // Create a PdfImageHelper object and get the image information on the page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Load the new image and replace the first image on the page
    let newImage = pdfModule.PdfImage.FromFile(newImageName);
    helper.ReplaceImage(images[0], newImage);

    // Define the output file name in PDF format
    const outputFileName = 'ReplaceImage.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName });
    doc.Close();

    // Read the generated PDF file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace Image In PDF</h1>
      <button onClick={replaceImageInPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document generated after replacing an image
Delete Images from a PDF
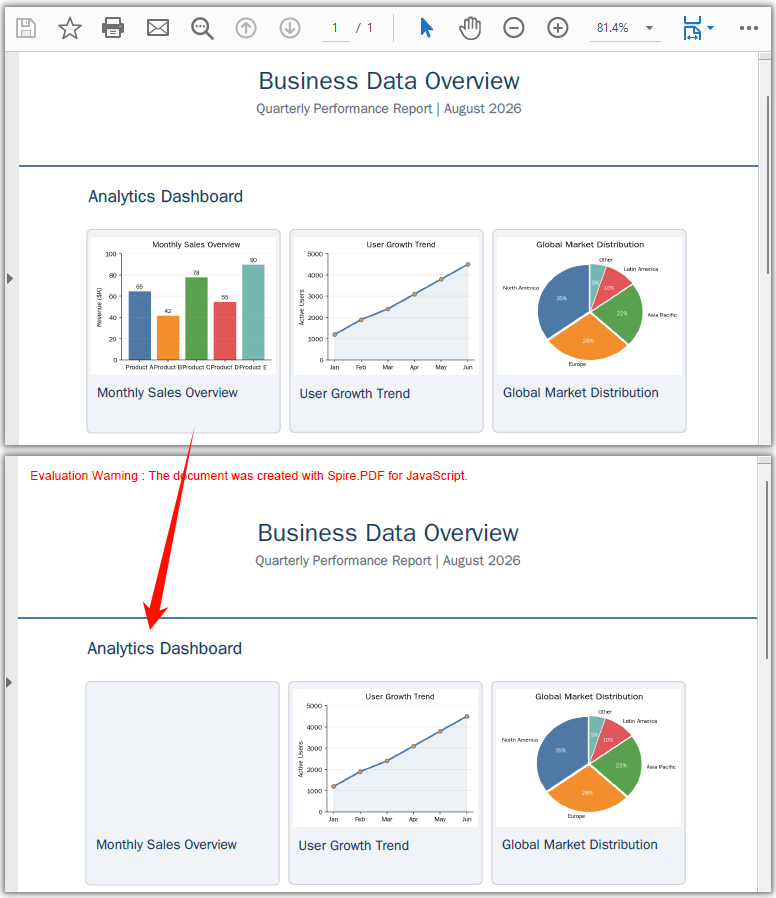
Deleting an image removes an image object that is no longer needed from the page. Similar to replacement, first use the GetImagesInfo method of PdfImageHelper to get the array of image information on the page, then call the DeleteImage method and pass in the corresponding image information object to delete the image. After deletion, the original position is left blank, and the text, graphics, and overall layout on the page are unaffected.
function App() {
  const deleteImageFromPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the first page
    let page = doc.Pages.get_Item(0);

    // Create a PdfImageHelper object and get the image information on the page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Delete the first image on the page
    helper.DeleteImage({ imageInfo: images[0] });

    // Define the output file name in PDF format
    const outputFileName = 'DeleteImage.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName });
    doc.Close();

    // Read the generated PDF file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Image From PDF</h1>
      <button onClick={deleteImageFromPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document generated after deleting an image
Extract Images from a PDF
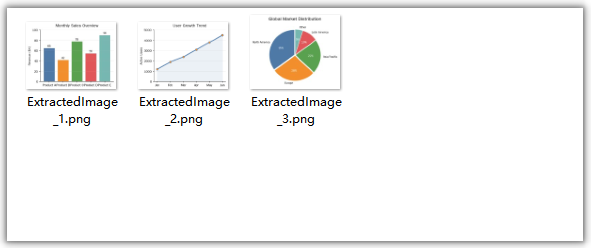
Extracting images exports existing images from PDF pages as separate image files, making them easy to reuse in other documents or systems. After getting the array of image information with the GetImagesInfo method of PdfImageHelper, access the Image property of each image information object one by one, call its Save method to save the image to VFS, then read the file from VFS and trigger download. Extraction is a read-only operation and does not modify the original PDF document.
function App() {
  const extractImagesFromPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the first page
    let page = doc.Pages.get_Item(0);

    // Create a PdfImageHelper object and get the image information on the first page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Iterate through the images on the page, save each as a separate image file, and trigger download
    for (let i = 0; i < images.length; i++) {
      const outputFileName = `ExtractedImage_${i + 1}.png`;
      images[i].Image.Save({ fileName: outputFileName });

      // Read the extracted image file from VFS and trigger download
      const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const blob = new Blob([fileArray], { type: 'image/png' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      a.click();
      URL.revokeObjectURL(url);
    }

    doc.Close();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract Images From PDF</h1>
      <button onClick={extractImagesFromPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
Image files extracted from the PDF
FAQ
How to identify which image to replace or delete
Reason: GetImagesInfo returns an array of information for all images on the page; the order of the array is related to how the images are arranged on the page.
Solution: You can access a specific image through the array index, for example images[0] represents the first image on the page; you can also read the Bounds property of the image information object to determine the region where the image is located, and then filter out the target image based on the position. The following example demonstrates how to delete images based on the region they occupy:
// Get the image information on the page
let helper = new pdfModule.PdfImageHelper();
let images = helper.GetImagesInfo(page);

// Iterate through the images and delete those within the specified region
for (let i = 0; i < images.length; i++) {
  let rect = new pdfModule.RectangleF({ x: 100, y: 300, width: 30, height: 40 });
  if (images[i].Bounds.IntersectsWith({ rect: rect })) {
    helper.DeleteImage({ imageInfo: images[i] });
  }
}
How to precisely control the position and size of an image when adding it
Reason: The coordinate and size parameters of DrawImage directly determine how the image is displayed on the page.
Solution: x and y are the coordinates of the top-left corner of the image, and width and height are the display size. To scale by the original proportion, first read image.Width and image.Height, then multiply by a scale factor to calculate the target size; to center the image, read page.Canvas.ClientSize.Width to calculate the horizontal coordinate, for example x = (page.Canvas.ClientSize.Width - width) / 2.
Will replacing or deleting images affect the text and other content in the PDF?
Reason: The replace and delete operations only act on the image objects themselves.
Solution: When replacing an image, the new image inherits the original image's position and placeholder size, and the rest of the page remains unchanged; after deleting an image, the original position is left blank, and the other text, graphics, and layout on the page are unaffected. Extracting images is a read-only operation and does not modify the original document.
Get a Free License
If you want to remove the evaluation messages in the resulting documents or get rid of functional limitations, contact sales to obtain a 30-day temporary license.